proxies for generalization: what survives in 1d when generalization gap is explicit?
This post closes the first group of posts built around the same 1d classification example. In that example, post 1 showed that useful explanations of generalization cannot ignore the data, and post 2 identified the exact quantity that remains at interpolation: Bayes error plus a disagreement term with the Bayes classifier.
That raises a natural question:
do popular complexity measures for generalization say something about the mass of the region where the classifier has the wrong sign, or are they really measuring something else?
All the complexity measures we look at do depend on the learned decision rule, so they are eligible candidates to explain generalization in this setup. In particular, they do not fall in the “data-agnostic” category of post 1. But being an eligible candidate is not the same as tracking the right object.
We stay in the same setup as before:
- $X\sim \mathrm{Unif}([-1,1])$
- label $y(x)=\operatorname{sign}(x)$
- with probability $p$, the label is replaced by a random sign $\text{Unif}(\{-1,+1\})$.
We train a 1-hidden-layer ReLU net for binary classification. Write its 2d output as $f(x)=(f_1(x),f_2(x))$. Define the logit gap
$$ \Delta(x)=f_2(x)-f_1(x), $$with predicted label
$$ \hat y(x) = \operatorname{sign}(\Delta(x)). $$The population error is (proved in the previous post):
$$ \boxed{ \text{population error}(p) = p/2 + (1-p)\,\mathrm{Leb\_wrong}/2 } $$with the Lebesgue measure of the disagreement set: $\mathrm{Leb\_wrong} = \mathrm{Leb}\{x\in[-1,1]: \operatorname{sign}(\Delta(x))\neq \operatorname{sign}(x)\}$.
This formula is the takeaway of post 2. Once training error is zero, the classifier-dependent part of generalization is controlled by the disagreement region: how much of the interval is predicted with the wrong sign. That is the quantity the proxies should somehow capture.
In more general classification settings, there is no similar easy formula since the Bayes classifier is not tractable. Instead, one falls back on proxies computed from the learned parameters: margins, counts of decision changes, slopes, sharpness, and related quantities.
But in our 1d example, these indirect explanations can be compared directly to the exact Bayes-disagreement formula above.
what do these proxies actually measure, compared with the quantity that really determines generalization here?
usual proxies and their computation
Since we consider a one-hidden-layer ReLU net, many complexity measures are easy to compute. Indeed, each ReLU hidden unit $x\mapsto \max(0,w x+b)$ is piecewise affine with a single breakpoint at
$$ x=-b/w. $$If we sort these breakpoints, we get a partition of the domain into intervals on which $\Delta$ is affine:
$$ \Delta(x)=m x + c. $$Computing all these intervals and the corresponding slopes $m$ and intercepts $c$ is easy, and allows to compute many proxies exactly, such as:
- the number of affine pieces,
- the number of sign changes of $\Delta$,
- slopes $\lvert m \rvert$ on each region, in particular, the exact Lipschitz constant $\max \lvert \Delta'(x) \rvert$, or the averaged Lipschitz constant $\int_{-1}^1 \lvert\Delta'(x)\rvert\,dx / 2$,
- margin-band mass $\mathrm{Leb}\{\lvert\Delta(x)\rvert\le \gamma\}$,
- the same slopes and margin bands after dividing $\Delta$ by its root-mean-square over $[-1,1]$, which removes the overall scale of the logits, and the corresponding normalized training margins,
- sharpness around the learned parameters,
- and of course $\mathrm{Leb\_wrong}$.
two families of proxies
In this setup, most of the proxies we look at fall into one of two broad families.
family A: decision-geometry proxies (about correctness of the decision)
These try to say something meaningful about the geometry of the disagreement set $\{x\in[-1,1]: \operatorname{sign}(\Delta(x))\neq \operatorname{sign}(x)\}$.
-
$\mathrm{Leb\_wrong}$ itself.
Not a proxy: it is the measure of the disagreement set, and yields the exact population error (up to the factor $(1-p)/2$), and thus also the generalization gap if the training error is zero. -
number of sign flips (roots) of $\Delta$.
A coarse summary of how often the classifier changes its mind on $[-1,1]$. This is not a standard generalization proxy in modern settings, but here it is a natural candidate to track the level of corruption $p$ at interpolation, since as $p$ grows, the learned rule needs to flip its decision more and more often to fit the corrupted labels. However, there is no direct link with $\mathrm{Leb\_wrong}$: you can flip a lot while being wrong on a tiny set, or flip rarely while being wrong on a large set. -
margin-band mass $$ \mathrm{Leb}\{x\in[-1,1]: |\Delta(x)|\le \gamma\}. $$ This measures how much input mass lives near the decision boundary $\Delta=0$. It says “how fragile are predictions under small perturbations in score”. It does not say “is the boundary placed correctly”. In particular, a classifier can be confidently wrong (large $|\Delta|$ with wrong sign), so band mass can be small while $\mathrm{Leb\_wrong}$ is large. So here, this unsigned band is mostly about robustness of the decision, not correctness. It differs from the signed training margins $y_i\Delta(x_i)$ studied in the margin literature, which are negative on misclassified points.
family B: scale / landscape proxies (about sensitivity of the decision, not correctness)
These are about “how wild” $\Delta$ is, or how sensitive the parameters are.
-
slope / Lipschitz-type quantities in input space.
Like the maximal slope $\max \lvert \Delta'(x) \rvert$ over all $x$, or the average slope $\int_{-1}^1 \lvert\Delta'(x)\rvert\,dx / 2$. Large slopes mean large sensitivity to input perturbations. However, sensitivity has no direct link with whether the decision is correct (there are classifiers with large slope but small disagreement mass, and vice versa).We report exact versions of these slopes. In general, computing the exact Lipschitz constant is NP-hard (Virmaux and Scaman, 2018), and upper bounds are often used instead.
-
flatness / sharpness in parameter space.
These measure how sensitive the training loss is to perturbations of the parameters. Sharpness can track memorization difficulty rather than disagreement geometry. Here, interpolating increasingly corrupted labels requires more and more oscillations of the learned rule, and small parameter perturbations can easily break these oscillations and cause large loss increase, even if the disagreement mass (hence generalization gap) remains small.These proxies are the only ones we consider that do depend on the parameters chosen to represent the learned decision rule. The ReLU network used for classification admits several parameter values that represent the same function. Among these parameters, some can be sharper than others. Below, we will report different notions of sharpness, each with different sensitivity to these symmetries.
which proxies are closest to the right geometry?
A complexity measure should help choose among models trained on the same data: given one training set, which of the networks that fit it will generalize better? So we fix the corruption level at $p=0.4$, fix a training set, train several networks on it, and ask whether a proxy orders them like their generalization gaps.
For networks that interpolate the training set, the formula above becomes
$$ \mathrm{gap}=0.2+0.3\,\mathrm{Leb\_wrong}, $$so $\mathrm{Leb\_wrong}$ orders them perfectly and serves as a reference.
Before looking at the numbers, we can already expect a rough hierarchy in this 1d setup:
- $\mathrm{Leb\_wrong}$ is exact, by the formula above.
- The sign-flip count is constrained by the training set: to interpolate, the learned rule must change sign at least once between consecutive training inputs with different labels. If the networks add no extra flips, the count is the same for all networks fitted to the same data, and cannot order them.
- Then should come sensitivity proxies such as margin-band mass, slopes, and sharpness, which are not directly about where the decision boundaries are placed.
results
We draw 20 training sets of 32 points at $p=0.4$. On each, we train 16 one-hidden-layer ReLU networks with Adam: widths 256 and 1024, initialization scales 0.5 and 2 (multiplying the default initialization), learning rates 0.003 and 0.01, and two random initializations. Training stops at zero training error and cross-entropy at most 0.02, within 200,000 steps.
232 of the 320 networks fit every training label. We keep the training sets with at least 8 such networks: 15 sets, 206 networks. For each training set, we compute the Spearman rank correlation between a proxy and the generalization gap, then average over the 15 training sets. The intervals are 95% bootstrap intervals over training sets.
The proxies, in the notation of the code:
nb_flips: number of sign changes of $\Delta$ on $[-1,1]$nb_regions: number of affine pieces of $\Delta$Lmax,Lavg: maximum and average of $\lvert\Delta'(x)\rvert$Lavg_flip: average of $\lvert\Delta'(x)\rvert$ over the affine pieces containing a root of $\Delta$band_mass_γ: margin-band mass $\mathrm{Leb}\{\lvert\Delta(x)\rvert\le\gamma\}$- normalized versions: the same quantities for $\Delta$ divided by its root-mean-square over $[-1,1]$. The normalized margins are the minimum and 10th percentile of the training margins $y_i\Delta(x_i)$ after this normalization. This normalization is a choice made for this experiment. It differs from those in the margin papers cited below.
flat_rel: mean training-loss increase under small relative Gaussian perturbations of the parameterssam_sharp: training-loss increase after one normalized gradient-ascent step of radius $10^{-3}$hess_top: top Hessian eigenvalue, estimated by power iteration
Proxies are sorted by the absolute value of their mean correlation:
| proxy | mean rank correlation with the gap | 95% interval |
|---|---|---|
Leb_wrong (reference) |
+1.00 | |
band_mass_γ, all four $\gamma\in\{0.1,0.2,0.5,1\}$ |
−0.37 to −0.38 | [−0.52, −0.22] |
Lavg_flip |
+0.24 | [+0.06, +0.42] |
normalized band_mass_0.1 |
−0.19 | [−0.40, +0.03] |
normalized band_mass_0.2 |
−0.18 | [−0.37, +0.02] |
normalized Lavg |
+0.18 | [−0.01, +0.36] |
flat_rel |
−0.14 | [−0.35, +0.08] |
normalized band_mass_0.5 |
−0.13 | [−0.35, +0.10] |
hess_top |
+0.09 | [−0.07, +0.26] |
Lavg |
+0.07 | [−0.18, +0.31] |
Lmax |
+0.07 | [−0.17, +0.28] |
normalized Lmax |
+0.03 | [−0.15, +0.19] |
normalized band_mass_1.0 |
+0.02 | [−0.17, +0.21] |
| normalized margin, 10th percentile | +0.02 | [−0.23, +0.26] |
nb_regions |
−0.02 | [−0.16, +0.12] |
| normalized margin, minimum | +0.01 | [−0.22, +0.25] |
sam_sharp |
−0.01 | [−0.14, +0.13] |
nb_flips |
constant in 13 of the 15 training sets |
The decision-flip count cannot order the networks. All but two of the 232 interpolating networks change sign exactly once between consecutive training inputs with different labels, and nowhere else. The count is then a property of the training set, identical for all networks fitted to it.
The next picture shows what it misses. Both networks fit the same 32 points with 11 decision boundaries, yet their gaps are 35.3% and 39.7%: the boundaries sit at different places between training points, so the wrong-sign intervals (shaded) have different lengths.
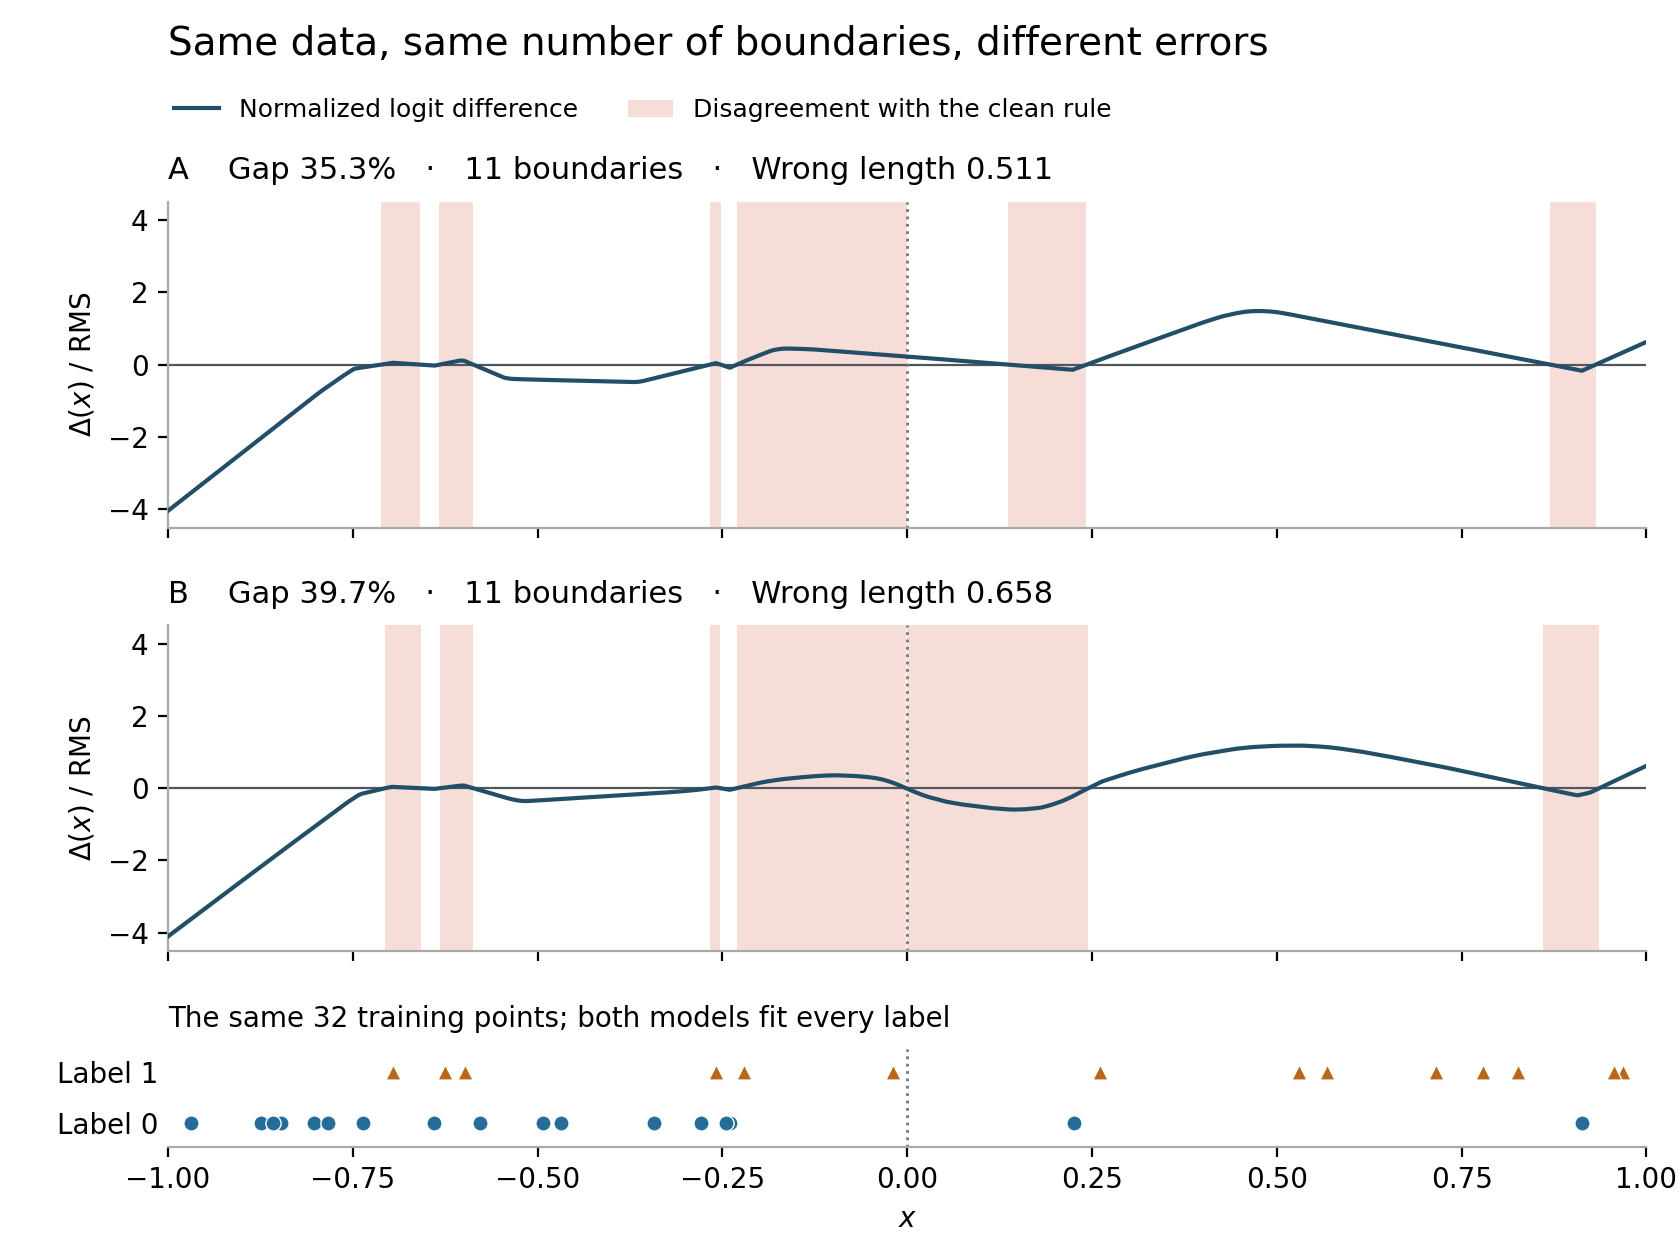
The pair with the largest gap difference among networks with the same flip count on the same training set, selected for contrast. Each curve is divided by its own root-mean-square, which changes its vertical scale but not its boundaries.
Raw margin-band mass and the slope at the decision boundaries show modest associations, but they measure different things. The band mass is the length of input where the logit difference is small, in units of the logits. Its association is negative: more input with a small logit difference goes with a smaller gap. It weakens once the logits are divided by their root-mean-square. The slope on the pieces where $\Delta$ crosses zero measures how steeply the decision changes, and its association is positive. Neither says where the boundaries are placed relative to the clean rule, which is what determines the gap. With correlations below 0.4 in absolute value over 15 training sets, neither ranks the networks reliably.
Sharpness, global slopes and the number of pieces show no clear association: their intervals contain zero.
The experiment covers one architecture, one noise level and a small set of hyperparameters, and only the networks that fit every training label. Wider networks and larger initializations reached zero training error more often.
Experiment script · all 320 runs · summary
takeaway
This closes the first group of posts built around understanding generalization in the same 1d classification example.
In that example, we now know the target exactly: at interpolation, the generalization gap equals the population error, namely Bayes error plus a term controlled by the mass of the region where the learned classifier disagrees with the Bayes rule. Most common proxies do not measure that quantity. Slopes measure sensitivity to inputs, margin bands to changes in scores, and sharpness to changes in parameters. The sign-flip count measures how often the prediction changes.
The experiment illustrates that. Among networks fitted to the same training set, only the exact geometric target orders them reliably. The decision-flip count is fixed by the training labels. The more generic proxies show weak associations at best: margin bands and slopes capture different geometric properties of the learned rule, but none of them is the geometry that determines generalization here, namely where the boundaries sit relative to the clean rule.
This is not specific to this 1d example: a fixed proxy only measures one aspect of the learned rule, and that aspect can be irrelevant to many Bayes-disagreement geometries that can arise in more general classification problems.
references
For large-scale studies of how generalization measures correlate with the gap of trained networks:
- Jiang et al., 2020 compute rank correlations (Kendall’s $\tau$) between many measures and the gap over thousands of networks trained on the same dataset. Their granulated version varies one hyperparameter at a time, with the others fixed, and averages the resulting correlations.
- Dziugaite et al., 2020 evaluate measures by their worst case over families of experiments rather than their average, since an average can hide systematic failures.
In this post, several hyperparameters vary at once within each training set, and the Spearman correlations are averaged over the 15 retained training sets, drawn independently from the same distribution. Above all, the gap is known in closed form, so a measure can be compared not only with the gap but with the geometry that determines it.
For the proxies themselves:
- margins: Bartlett, Foster and Telgarsky, 2017, Jiang et al., 2019
- input-space slopes and margins: Sokolić et al., 2017
- norms, margins and sharpness compared on the same networks, including loss increases under Gaussian parameter perturbations scaled by the weights (as in
flat_rel): Neyshabur et al., 2017 - sharpness: Keskar et al., 2017, and its dependence on the parametrization: Dinh et al., 2017
- the one-step sharpness approximation used for
sam_sharp: Foret et al., 2021 - number of linear regions, as a measure of expressive capacity rather than of generalization: Montúfar et al., 2014
- fitting random labels, the starting point of post 1: Zhang et al., 2017
cite this post as:
@misc{gonon2026proxies1d,
  title  = {Proxies for Generalization: What Survives in 1d When Generalization Gap Is Explicit?},
  author = {Antoine Gonon},
  year   = {2026},
  url    = {https://dimension-one.github.io/blog/2026-04-13-proxies-generalization-1d/}
}